Targeting a sequence is the beginning of an edit
Genome editing changes DNA at a chosen location or set of locations. CRISPR-based systems are especially useful because a guide RNA can help direct an associated protein to a target. Changing the guide can change the intended address, although the requirements depend on the particular editing system. [1]
The address does not specify the complete outcome. A conventional cutting system creates a molecular event that the cell must then respond to. Delivery, target recognition, DNA repair and the behaviour of the resulting cells all affect what the experiment achieves. This is why a headline about “precise scissors” captures only one part of the process. The final biological result needs to be measured separately from whether the editing machinery reached the intended region.
Guide RNA and the enzyme perform different jobs
In a commonly used Cas9 system, the guide includes a region that can pair with a target DNA sequence and a structural region that interacts with the Cas protein. Recognition also depends on a nearby sequence called a protospacer adjacent motif, or PAM. The required PAM differs among enzymes and variants, so the targeting rules are not identical for every CRISPR system. [2]
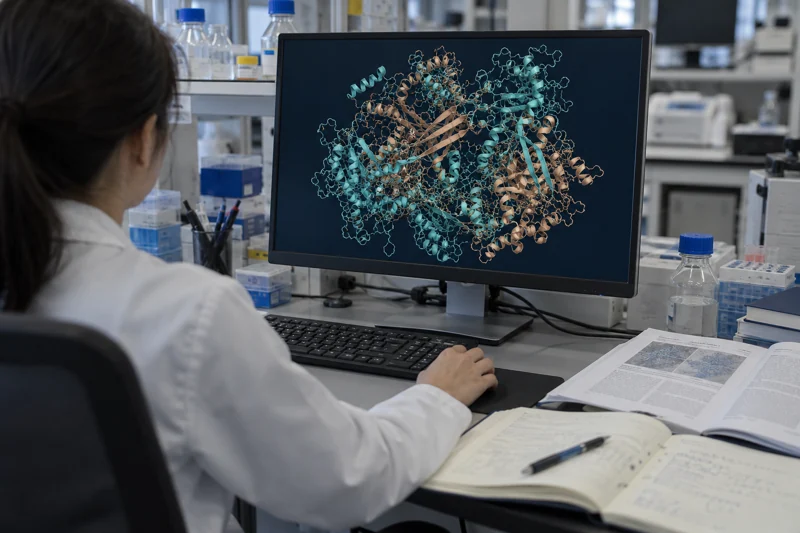
These requirements turn sequence recognition into a chemical problem. Bases must form suitable interactions, the protein must adopt an appropriate arrangement and the DNA must be accessible in the cellular environment. A target that appears attractive in a sequence list still needs experimental evaluation. The guide provides a programmable element, but the surrounding molecular system determines what that programming can accomplish.
A DNA break creates several possible repair outcomes
When both DNA strands are cut, cells can repair the break through different pathways. End joining can produce small insertions or deletions at the site. Repair using a suitable template can, under appropriate conditions, introduce a specified change. The balance depends on cell type, state and the system used. [2]
That distinction explains why “editing efficiency” needs a definition. A high fraction of DNA molecules showing any change is different from a high fraction carrying the intended sequence. A change at the chosen position may disrupt a gene, leave its function largely intact or have another effect depending on the exact result. Sequencing and functional measurements answer different parts of the question.
An invented dataset shows why the denominator matters
Imagine analysing 100 cells after an editing experiment. Forty show a detectable change at the target. Of those, 25 carry the intended sequence and 15 carry other changes. On this simplified cell-based accounting, the fraction with any target-site change is 40%, while the intended-outcome fraction is 25% of all analysed cells. Neither number is the same as 25 out of 40, or 62.5%, among the cells already classified as changed.
Real measurements can be more complicated because cells may contain more than one copy of a target and sequencing often counts DNA molecules rather than cells. The invented example is not a performance claim for a particular editor. It shows why readers need to know what was counted, which outcomes were included and which denominator produced the headline percentage.
Delivery is a separate molecular engineering task
The editing machinery must reach the relevant cells in a usable form. A protein–RNA complex, messenger RNA encoding an editor or another delivery format creates different timing and exposure conditions. The route into a cell can be as important as the choice of guide, particularly when the target is a specific tissue inside a body.
Delivery also affects interpretation of a negative result. If the machinery does not reach enough cells, failure to observe the intended change says little about the target mechanism. Conversely, a strong editing result in an accessible laboratory cell type does not establish that the same system will reach another tissue effectively. Comparing methods requires separating delivery, editing and the biological response that follows.
Specificity includes more than one kind of unintended outcome
Off-target activity refers to changes at other genomic locations, but assessment of unwanted outcomes does not end there. The intended site can also acquire changes that differ from the desired edit. Cells can vary in their response, and selecting a surviving population can change what is eventually measured.
An appropriate evaluation therefore examines the target sequence, plausible alternative sites and relevant broader consequences using methods suited to the claim. A statement that one predicted off-target site showed no change is narrower than a claim of no unintended effects anywhere. The useful scientific question is what was tested, how sensitively and in which cells. Specificity is an empirical property of an editing system under stated conditions, not an automatic consequence of choosing a guide.
Not every CRISPR-based tool makes the same DNA cut
The familiar Cas9 cutting example is one part of a larger family. Researchers have adapted CRISPR-associated proteins to regulate genes or to support other kinds of sequence change. Addgene's guide describes several uses and variants. [2] Different tools create different intermediates and therefore different questions about intended outcomes, byproducts and limits.
This is a reason to read the name of the method carefully. Evidence from one editor cannot automatically establish the performance of another, even when both are called CRISPR. A useful comparison identifies the exact molecular task, the cell population and the method used to measure success. The broad category describes a flexible research platform; the detailed system determines which result is actually being tested.
Somatic and heritable applications raise different questions
Editing a person's somatic cells concerns cells whose changes are not intended to be passed to future generations. Heritable or germline-related applications involve a different set of biological and ethical questions. NHGRI distinguishes these categories when explaining uses of genome editing. [3]
The distinction should not be reduced to one universal claim that genome editing is either acceptable or unacceptable. A specific proposal has a purpose, a tissue, an exposure and a set of possible consequences. Assessing a research application, an approved treatment and a proposed heritable intervention requires different evidence and governance. This article explains mechanisms and experimental interpretation; it does not establish the suitability of any intervention for an individual.
Why the chemistry matters beyond the laboratory
Genome editing brings together molecular recognition, protein function, nucleic-acid chemistry and delivery materials. Understanding those connections makes it easier to evaluate claims in medicine, agriculture and basic biology. It also reveals where an appealing idea still depends on an unresolved technical step.
The most informative account follows the whole chain: the machinery reaches the intended cells, recognizes the intended site, creates the intended change and produces a useful measured effect. Each step needs evidence. Treating them separately does not diminish the technology's importance. It explains why different studies can use similar molecular tools yet support very different conclusions about what is ready for practical use.
Delivery, editing outcome and biological response all shape what a genome-editing experiment can show.
Sources & further reading
Numbered references connect claims to their source. The main text is our original explanation; conceptual examples are identified as imagined.
- National Human Genome Research Institute — What is genome editing?Government research institute · foundational reference
- Addgene — CRISPR guideNonprofit research resource · targeting and DNA repair
- NHGRI — How is genome editing used?Government research institute · applications and somatic/germline distinction
Source review: 30 Oct 2026. Editorial standards.